Jump to preprints or selected publications.
Preprints
Selected Publications
Beyond Tabula Rasa: Reincarnating Reinforcement Learning
Rishabh Agarwal, Max Schwarzer, Pablo Samuel Castro, Aaron Courville, Marc G. Bellemare
NeurIPS 2022
This work proposes an alternative research workflow to tabula rasa RL, where prior computational work (e.g., learned policies) is transferred from agent to another.
Deep RL at the Edge of the Statistical Precipice
Rishabh Agarwal, Max Schwarzer, Pablo Samuel Castro, Aaron Courville, Marc G. Bellemare
NeurIPS 2021 (Outstanding Paper Award)
Our findings call for a change in how we evaluate performance on deep RL benchmarks, for which we present more reliable protocols and an
open-source library , easily applicable with *even a handful of runs*, to prevent unreliable results
from stagnating the field.
Contrastive Behavioral Similarity Embeddings for Generalization in Reinforcement Learning
Rishabh Agarwal, Marlos C. Machado, Pablo Samuel Castro, Marc G. Bellemare
ICLR 2021 (Spotlight)
To improve generalization, we learn representations, via a contrastive loss, that puts states together with similar long-term optimal behavior. This is orthogonal to existing
approaches such as data augmentation. An earlier version was accepted as an oral presentation at NeurIPS 2020 Workshop on Biological and Artificial RL.
Implicit Under-Parameterization Inhibits Data-Efficient Deep Reinforcement Learning
Aviral Kumar*, Rishabh Agarwal*, Dibya Ghosh, Sergey Levine
ICLR 2021
We identify an implicit under-parameterization phenomenon in value-based deep RL methods that use bootstrapping: when value functions,
approximated using deep neural networks, are trained with gradient descent using iterated regression onto target values generated by
previous instances of the value network, more gradient updates decrease the expressivity of the current value network.
RL Unplugged: Benchmarks for Offline Reinforcement Learning
Caglar Gulcehre, Ziyu Wang, Alexander Novikov, Tom Le Paine, Sergio Gómez Colmenarejo, Konrad Zolna, Rishabh Agarwal,
Josh Merel, Daniel Mankowitz, Cosmin Paduraru, Gabriel Dulac-Arnold, Jerry Li, Mohammad Norouzi, Matt Hoffman, Ofir Nachum,
George Tucker, Nicolas Heess, Nando de Freitas
NeurIPS 2020
We propose a benchmark called RL Unplugged to evaluate and compare offline RL methods on a diverse range of domains. We provide detailed evaluation
protocols for each domain and provide an extensive analysis of existing methods using these protocols. We hope that our suite of benchmarks will
increase the reproducibility in offline RL and make it possible to study challenging tasks with a limited computational budget, thus making RL research
both more systematic and more accessible across the community.
An Optimistic Perspective on Offline Reinforcement Learning
Rishabh Agarwal, Dale Schuurmans, Mohammad Norouzi
ICML 2020 (Talk)
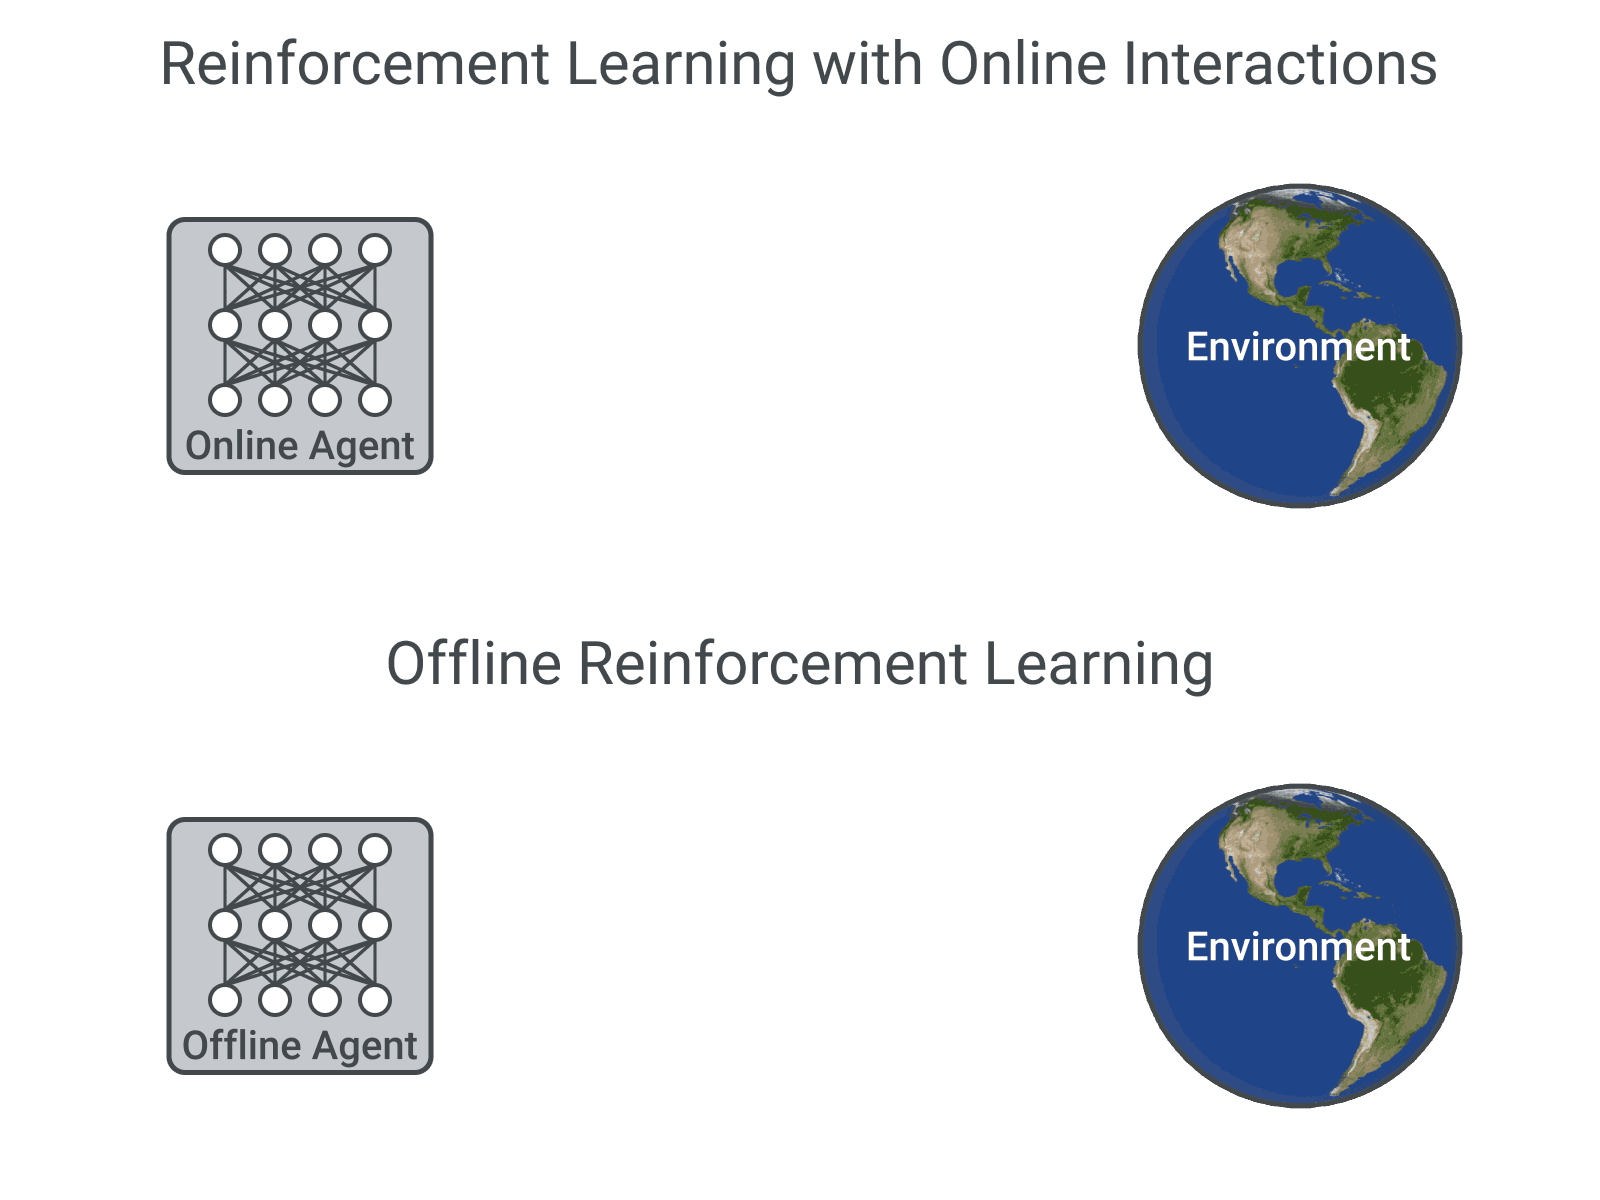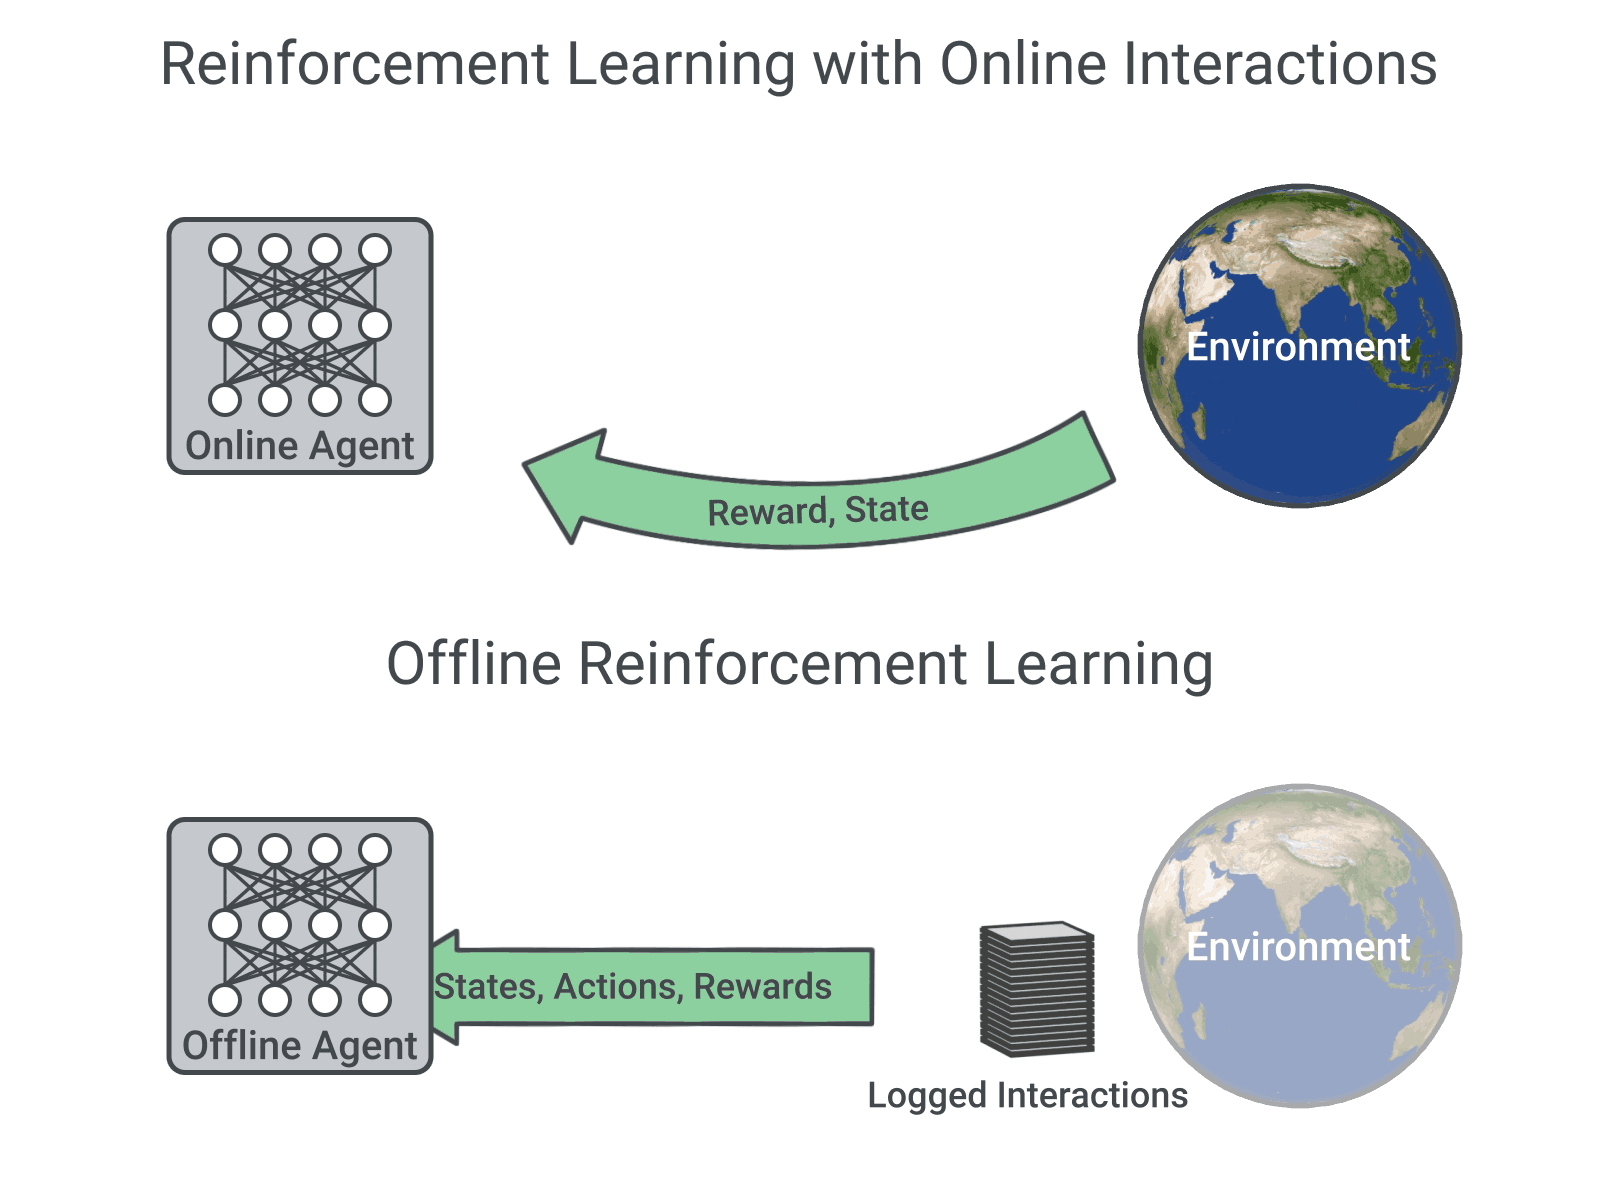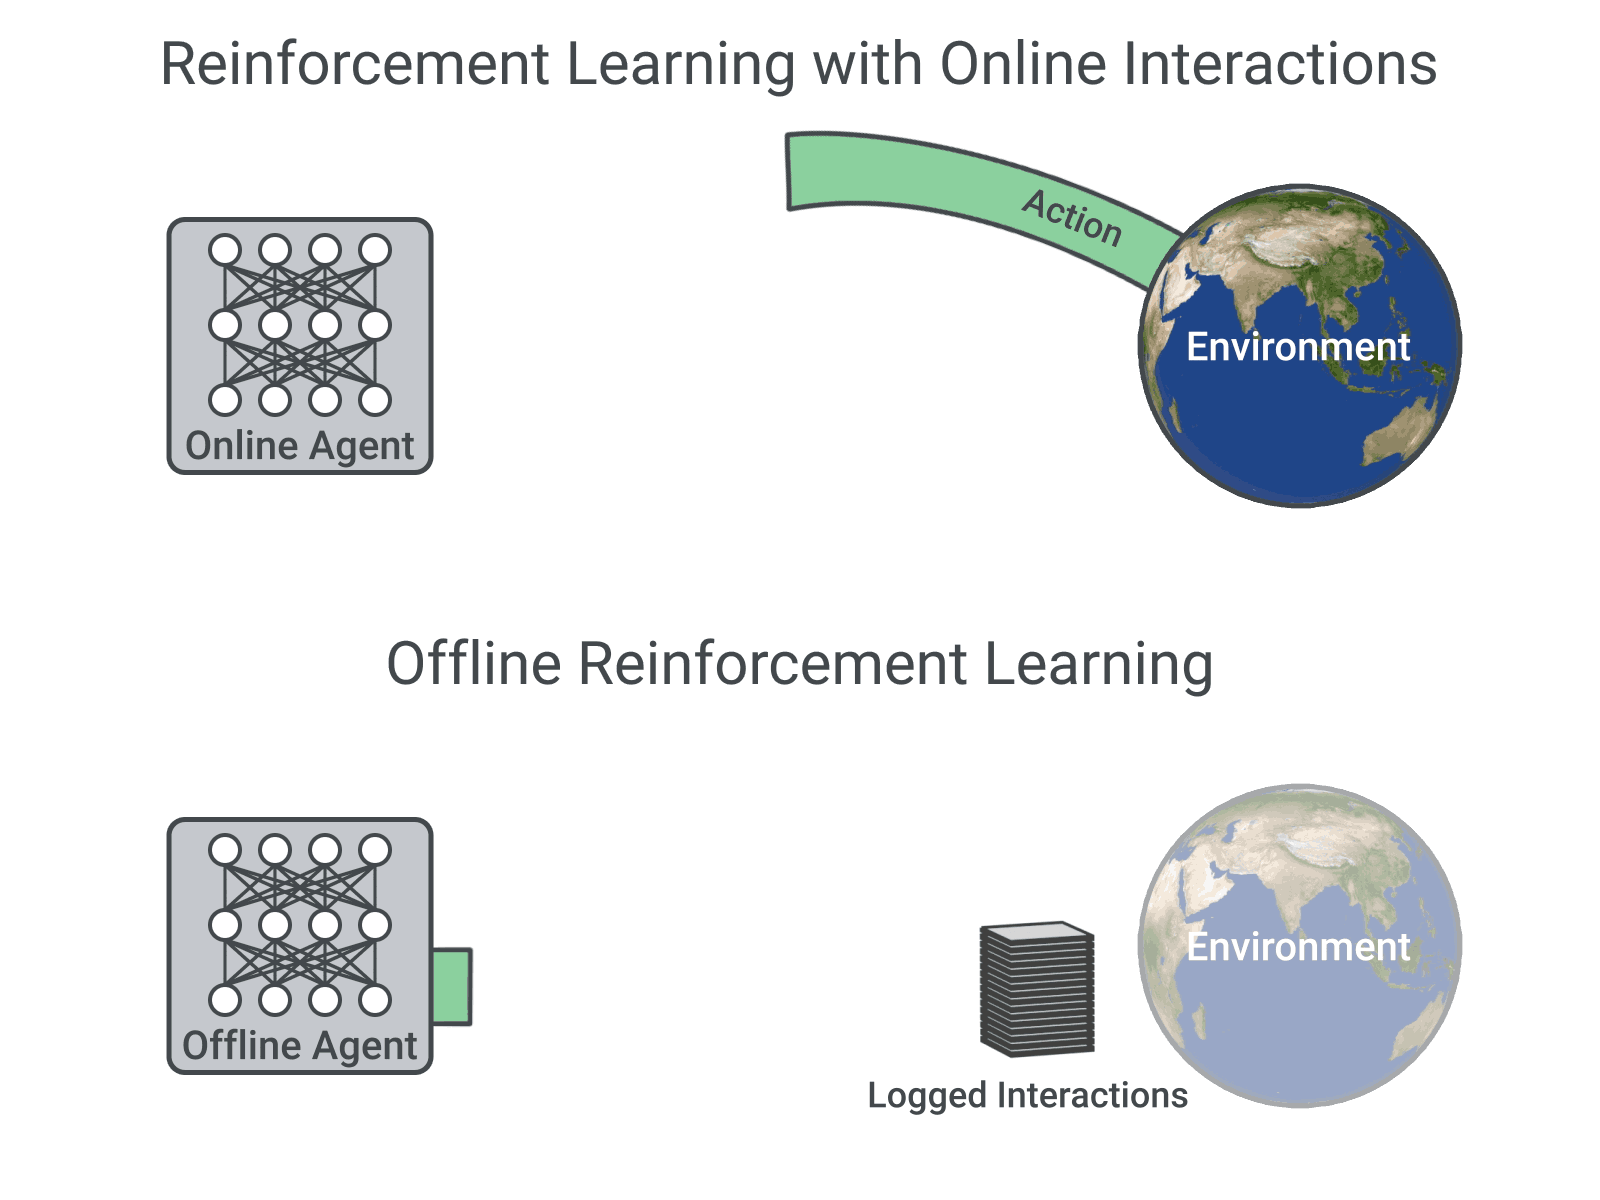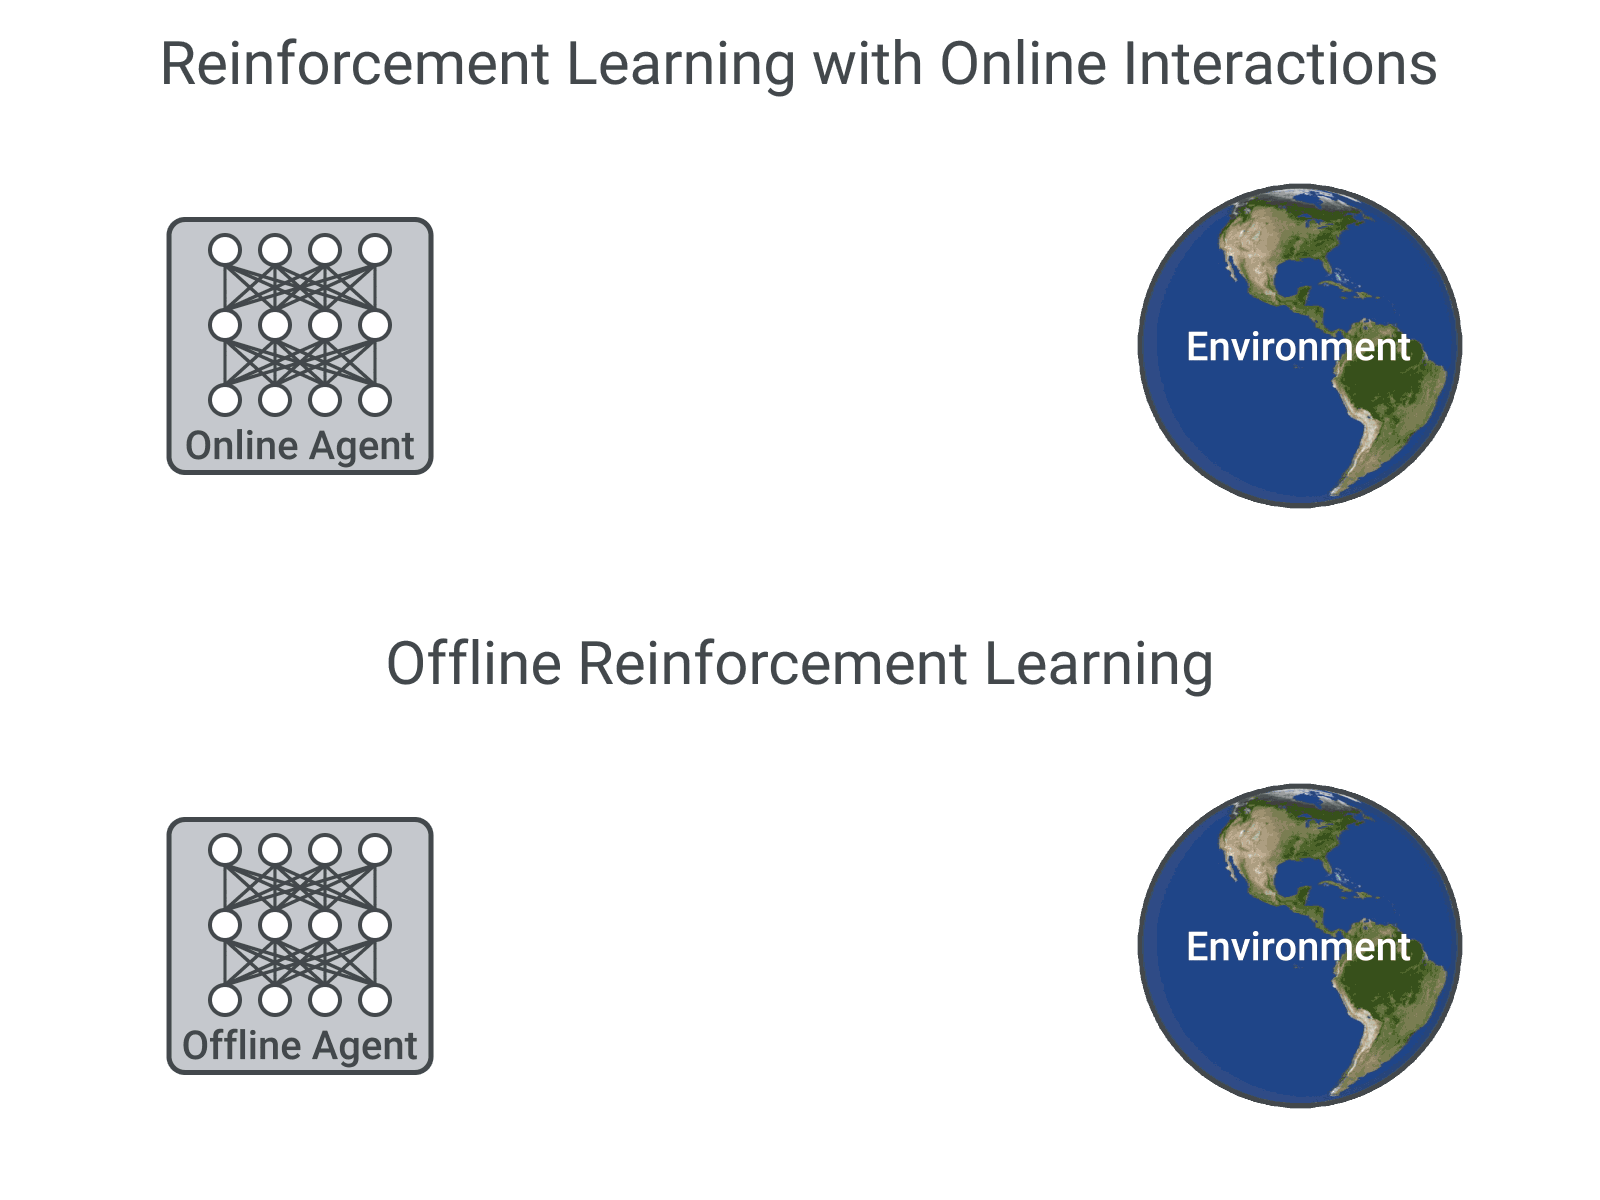
This paper popularized offline RL and showed that standard off-policy algorithms perform quite well in the fully
off-policy / offline deep RL setting with large and diverse datasets. A previous version was titled "Striving for Simplicity in Off-Policy Deep Reinforcement Learning"
and presented as a contributed talk at NeurIPS 2019 DRL workshop.
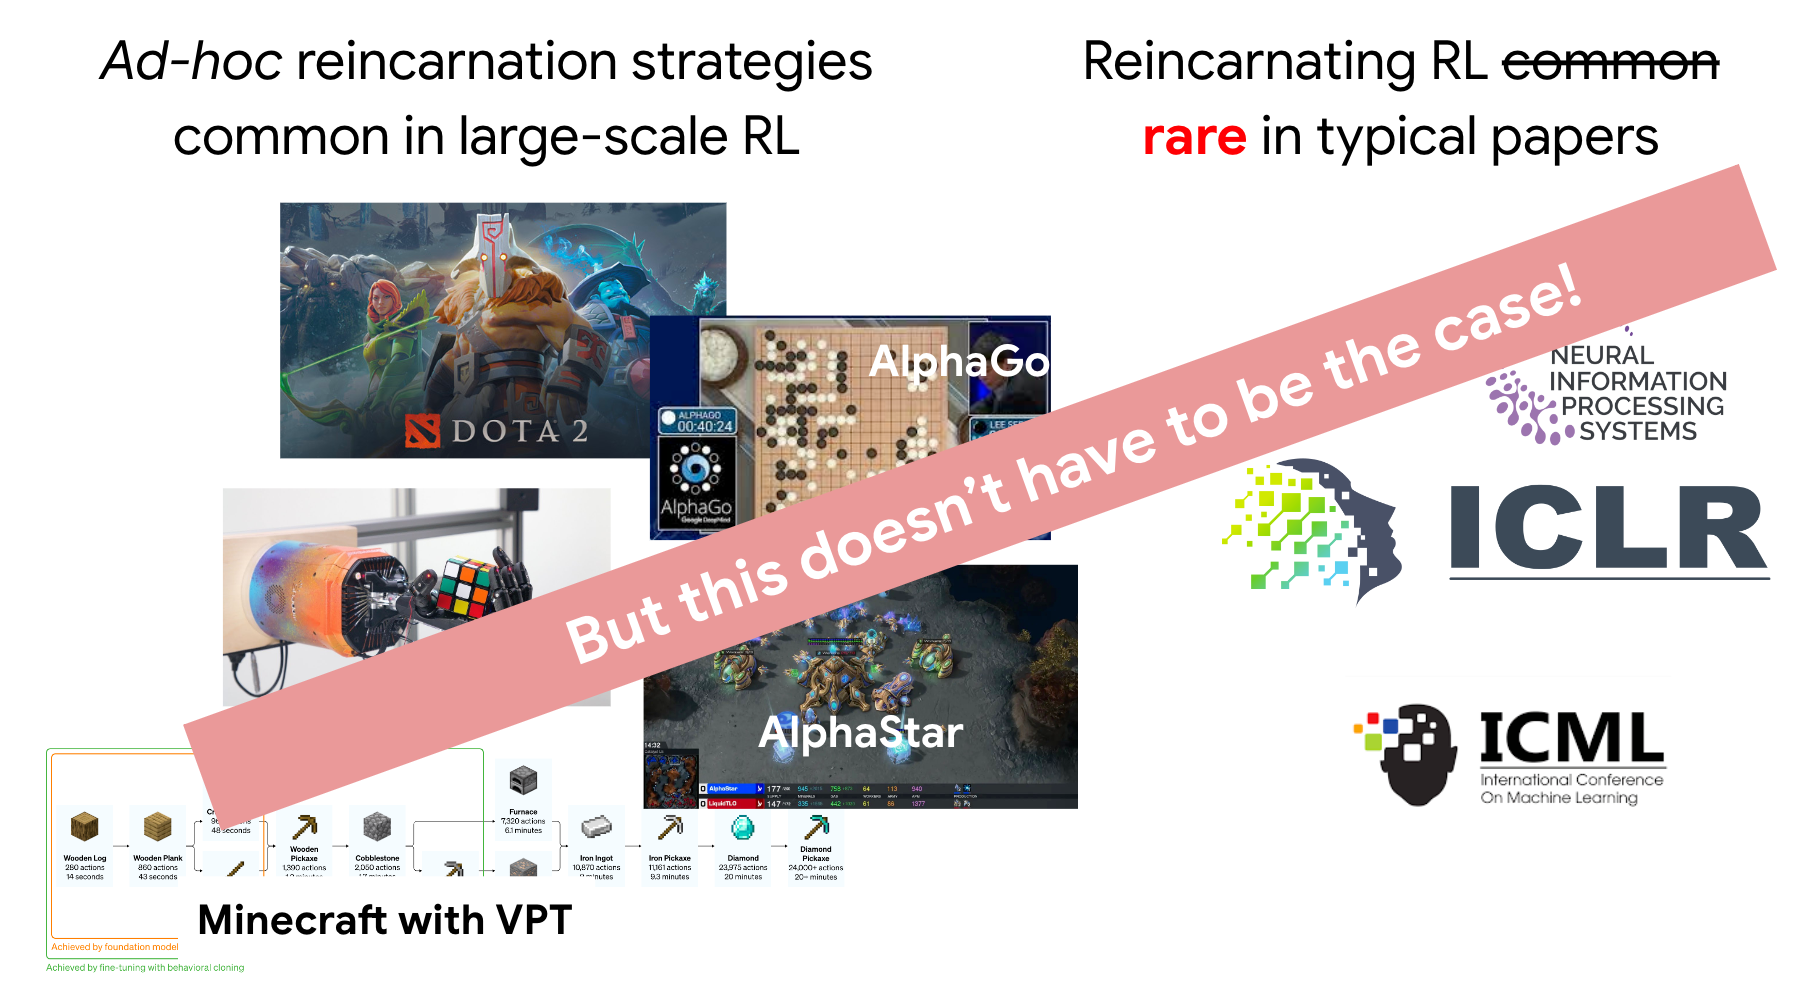
Rishabh Agarwal, Max Schwarzer, Pablo Samuel Castro, Aaron Courville, Marc G. Bellemare
NeurIPS 2022
This work proposes an alternative research workflow to tabula rasa RL, where prior computational work (e.g., learned policies) is transferred from agent to another.
Rishabh Agarwal, Max Schwarzer, Pablo Samuel Castro, Aaron Courville, Marc G. Bellemare
NeurIPS 2021 (Outstanding Paper Award)
Our findings call for a change in how we evaluate performance on deep RL benchmarks, for which we present more reliable protocols and an open-source library , easily applicable with *even a handful of runs*, to prevent unreliable results from stagnating the field.
Rishabh Agarwal, Marlos C. Machado, Pablo Samuel Castro, Marc G. Bellemare
ICLR 2021 (Spotlight)
To improve generalization, we learn representations, via a contrastive loss, that puts states together with similar long-term optimal behavior. This is orthogonal to existing approaches such as data augmentation. An earlier version was accepted as an oral presentation at NeurIPS 2020 Workshop on Biological and Artificial RL.
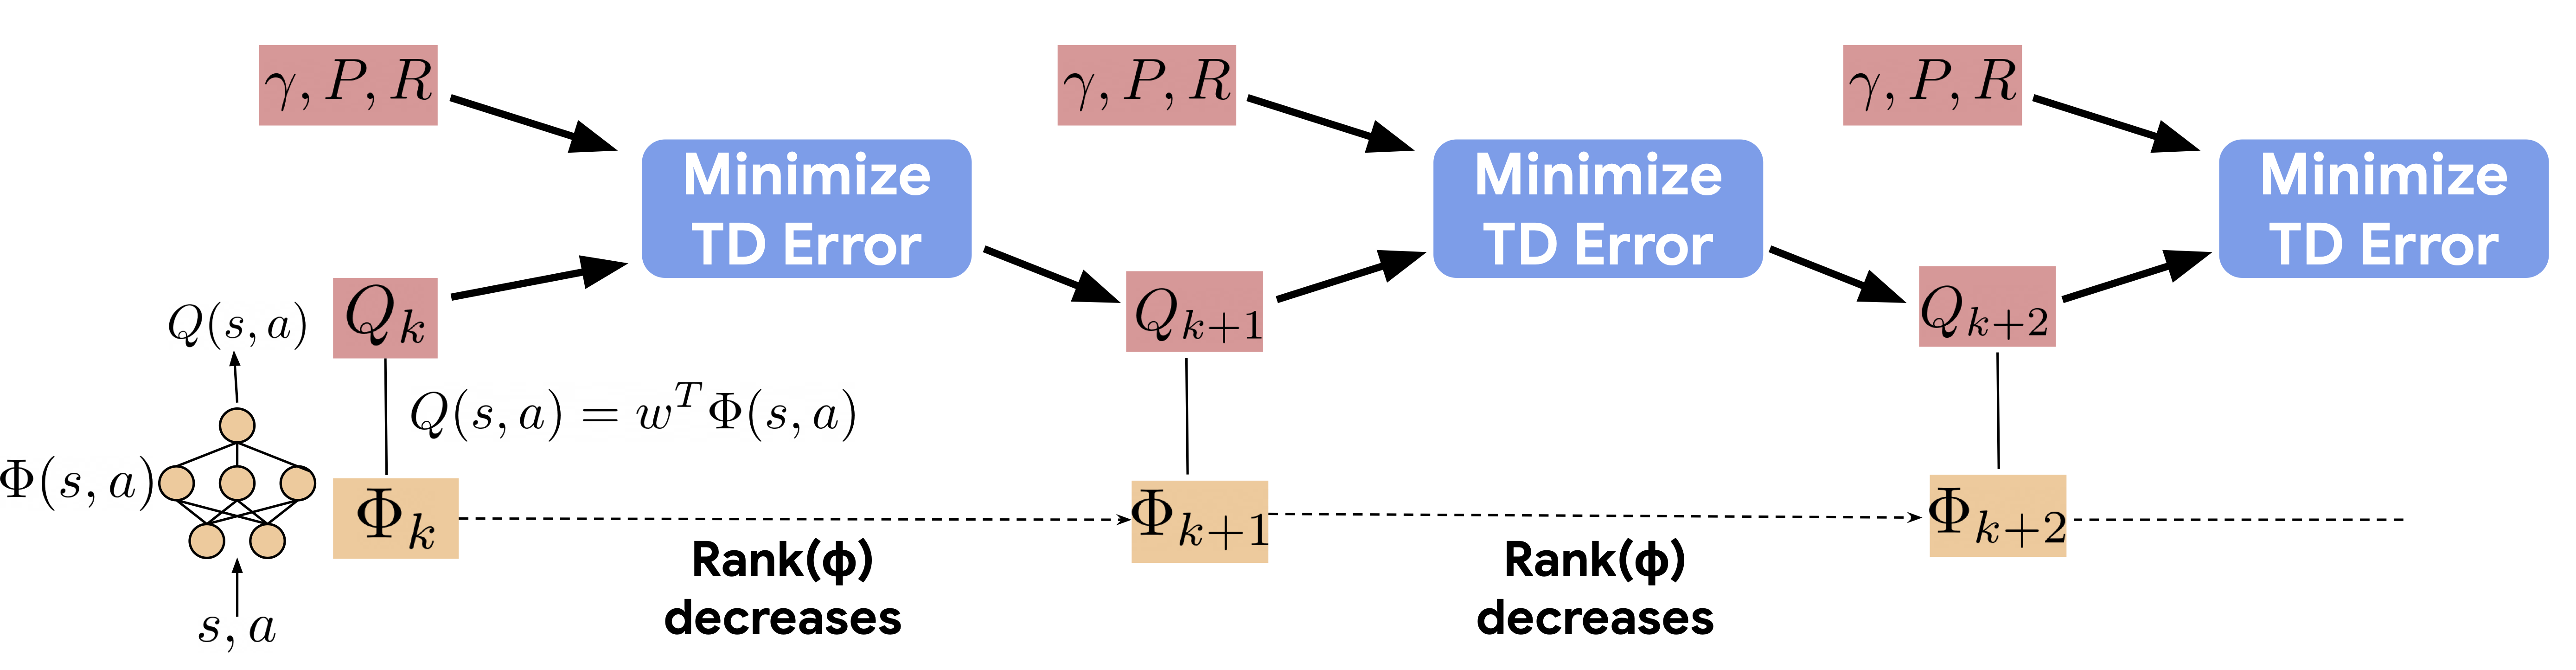
Aviral Kumar*, Rishabh Agarwal*, Dibya Ghosh, Sergey Levine
ICLR 2021
We identify an implicit under-parameterization phenomenon in value-based deep RL methods that use bootstrapping: when value functions, approximated using deep neural networks, are trained with gradient descent using iterated regression onto target values generated by previous instances of the value network, more gradient updates decrease the expressivity of the current value network.
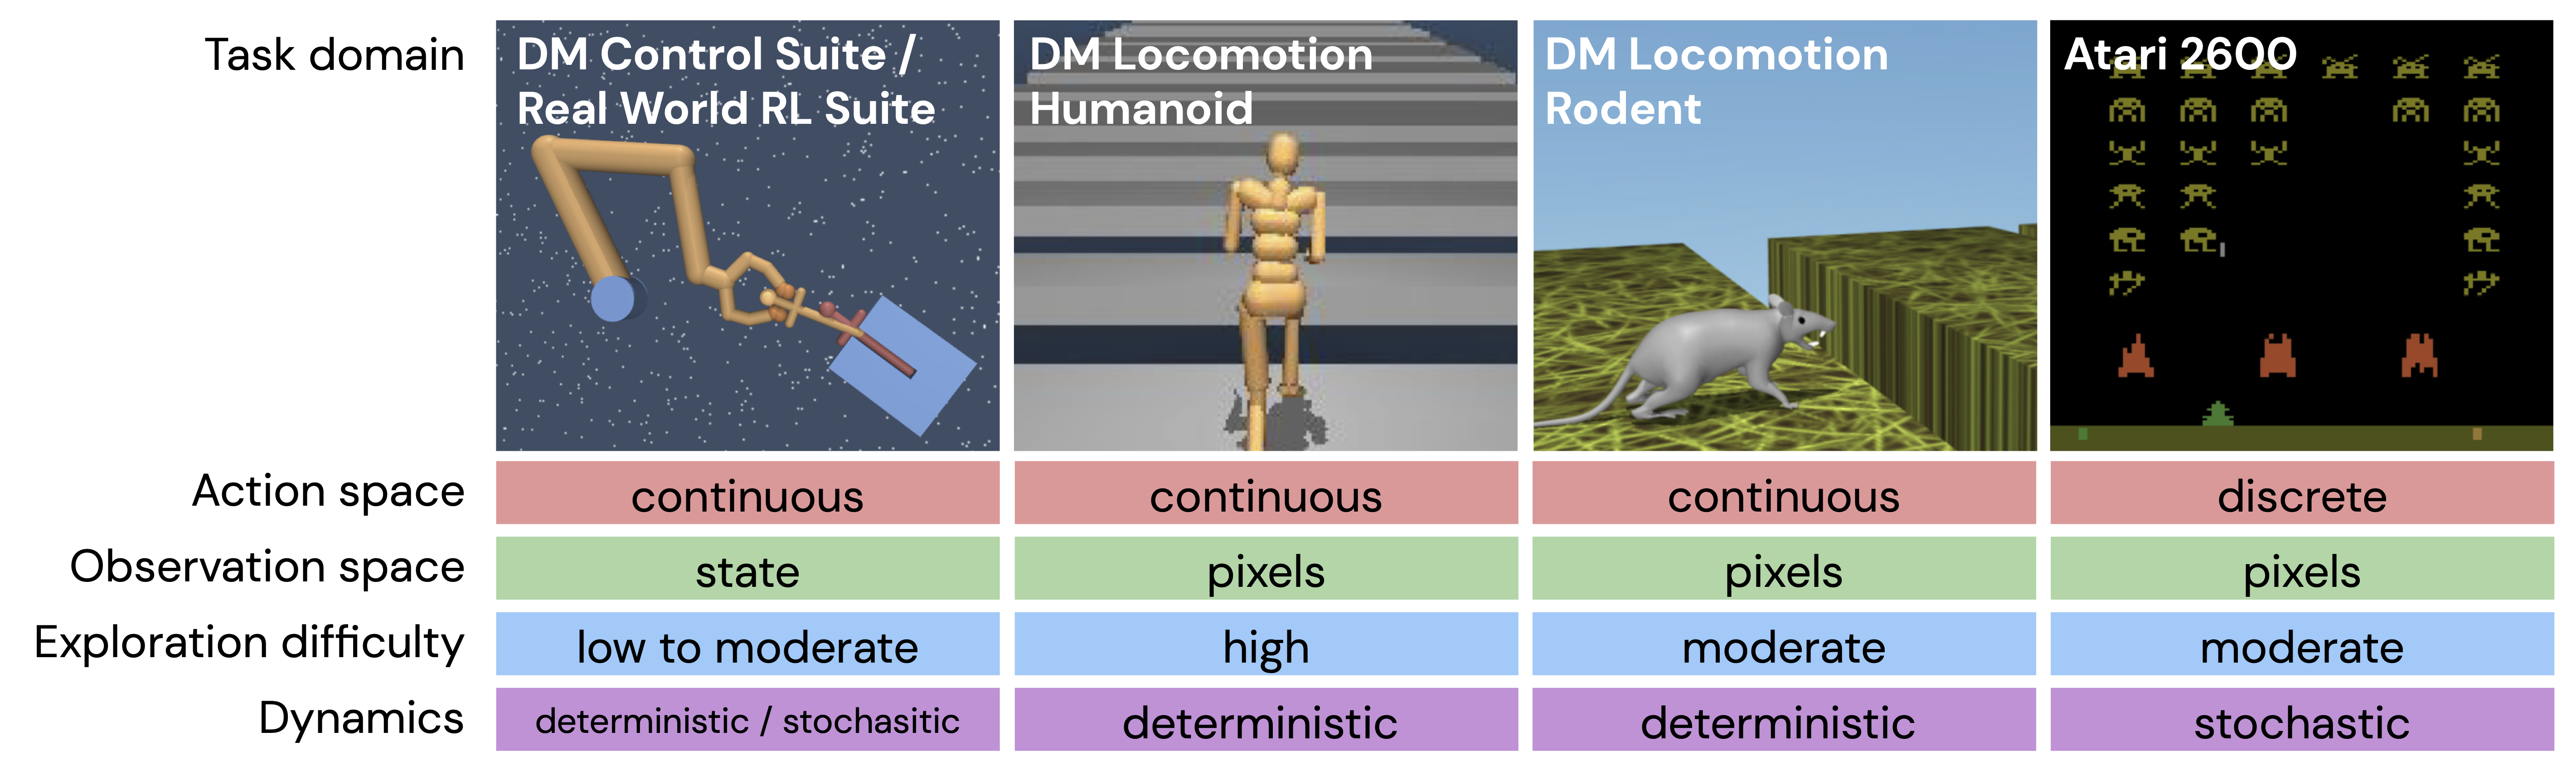
Caglar Gulcehre, Ziyu Wang, Alexander Novikov, Tom Le Paine, Sergio Gómez Colmenarejo, Konrad Zolna, Rishabh Agarwal,
Josh Merel, Daniel Mankowitz, Cosmin Paduraru, Gabriel Dulac-Arnold, Jerry Li, Mohammad Norouzi, Matt Hoffman, Ofir Nachum,
George Tucker, Nicolas Heess, Nando de Freitas
NeurIPS 2020
We propose a benchmark called RL Unplugged to evaluate and compare offline RL methods on a diverse range of domains. We provide detailed evaluation protocols for each domain and provide an extensive analysis of existing methods using these protocols. We hope that our suite of benchmarks will increase the reproducibility in offline RL and make it possible to study challenging tasks with a limited computational budget, thus making RL research both more systematic and more accessible across the community.
Rishabh Agarwal, Dale Schuurmans, Mohammad Norouzi
ICML 2020 (Talk)
This paper popularized offline RL and showed that standard off-policy algorithms perform quite well in the fully off-policy / offline deep RL setting with large and diverse datasets. A previous version was titled "Striving for Simplicity in Off-Policy Deep Reinforcement Learning" and presented as a contributed talk at NeurIPS 2019 DRL workshop.